Govern LLM Spend Before It Reaches Provider Bills
Cloptima gives platform and finance teams one control plane for AI gateway policies, bring-your-own-key access, cost-aware guardrails, response caching, and agent cost attribution.
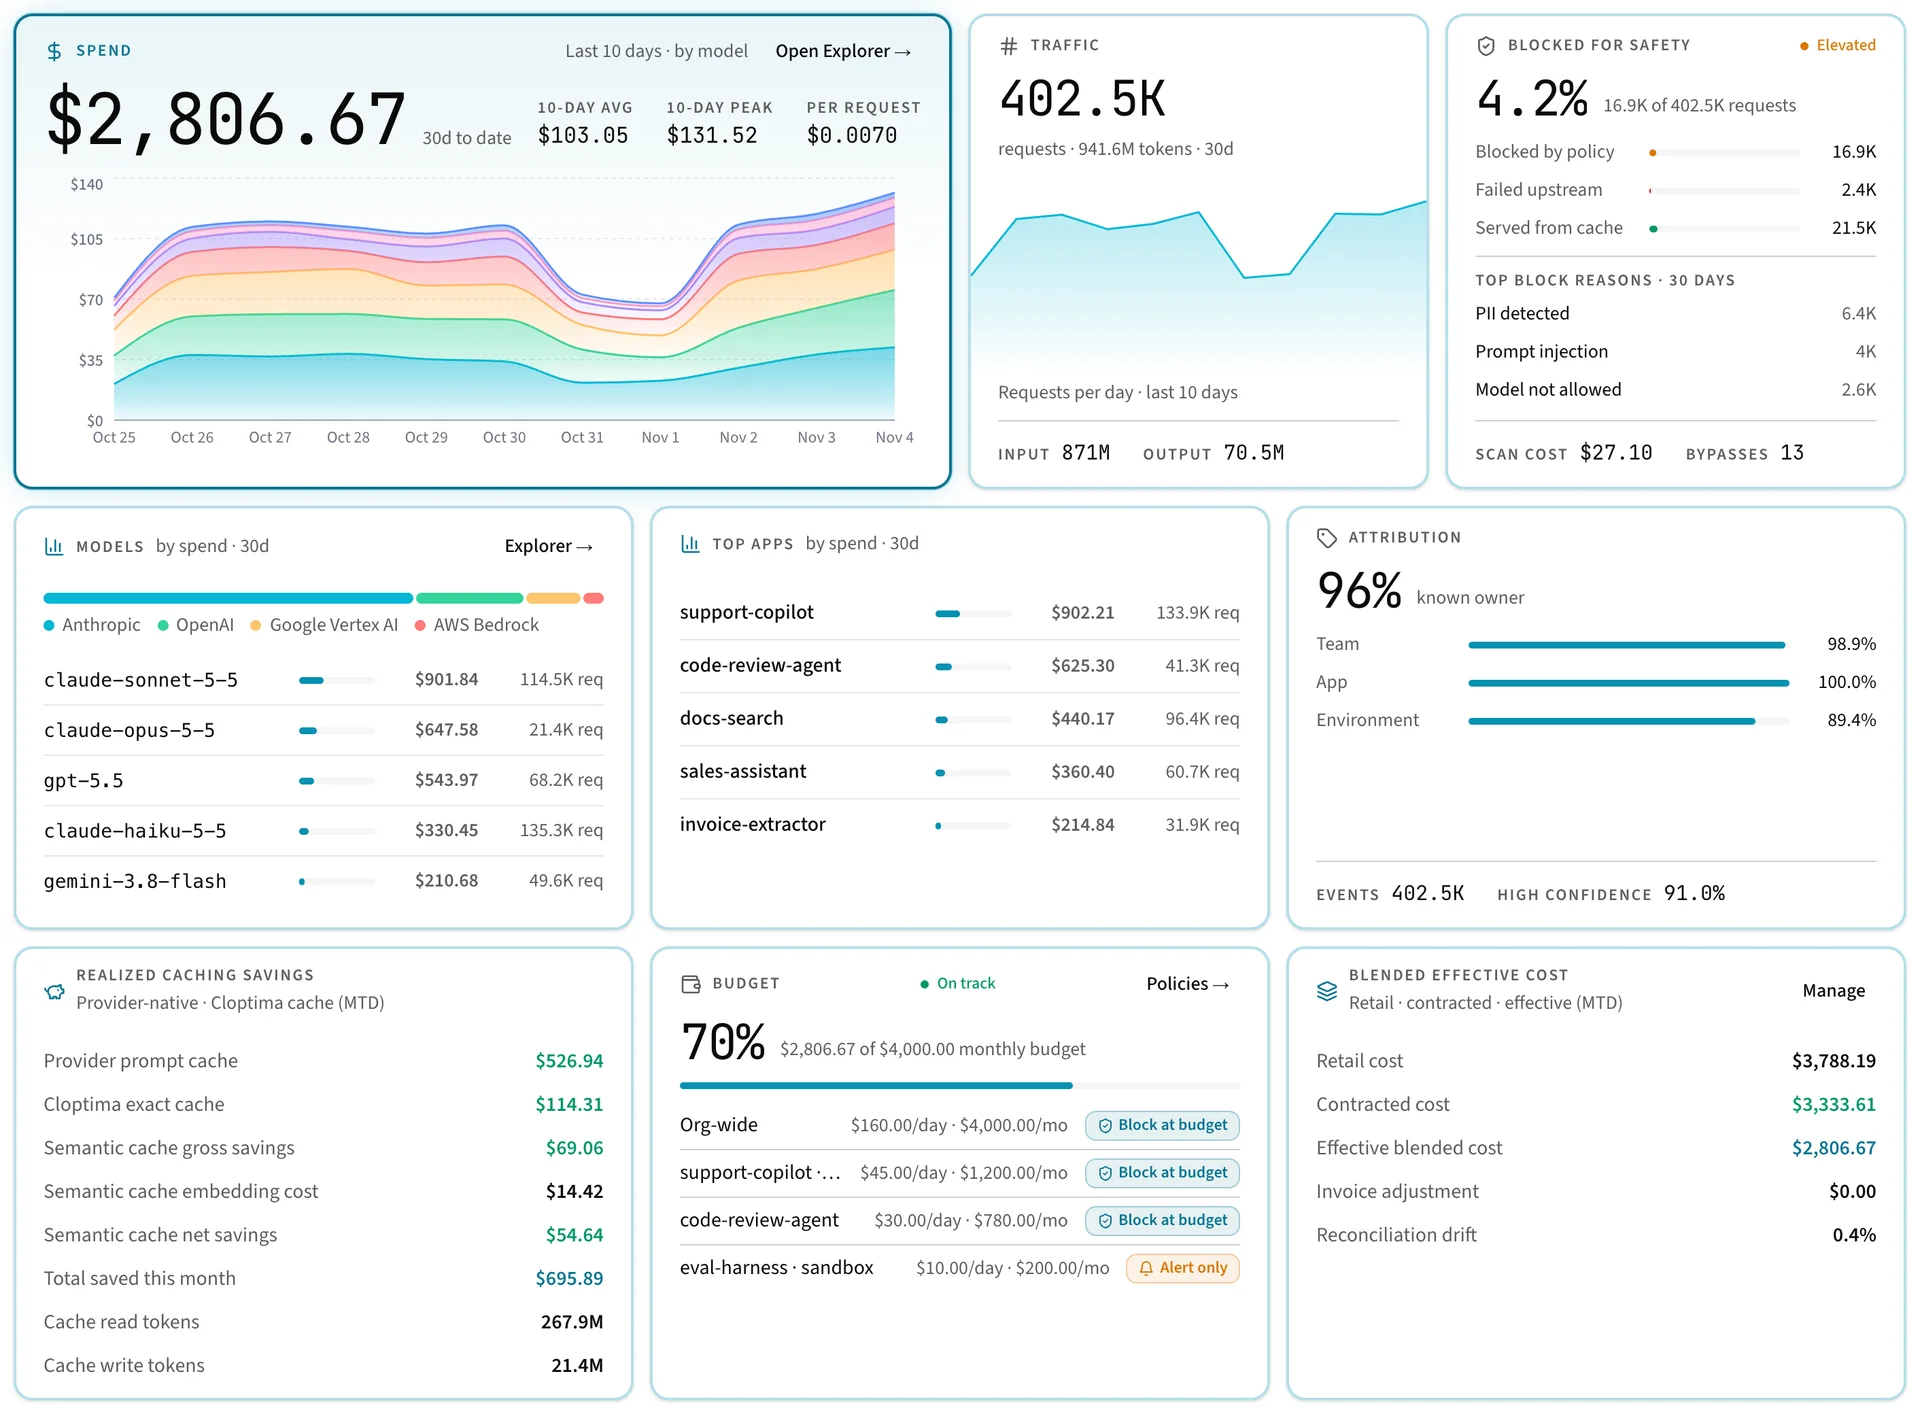
Pick where you are today
Every area is live and in production unless marked Coming Soon.
Gateway & Access
The governed entry point for every model call — routing, credentials, and budget enforcement.
Enterprise AI Gateway — Governed LLM Routing & Spend Control
Route model traffic through an OpenAI-compatible gateway with virtual keys, budgets, attribution, provider access controls, no-retention prompt policy, and attributed usage records.
BYOKBYOK for Model Provider Access
Centralize OpenAI, Anthropic, Gemini, Vertex AI, and Bedrock credentials behind encrypted controls while giving developers governed virtual-key access through Cloptima.
BudgetsLLM Budget Controls — Hot-Path Spend Limits & Token Quotas
Enforce hard spend ceilings, rate limits, and per-request token caps before provider calls egress. Prevent unexpected bills with atomic pre-flight reservations, one org-wide ceiling, and budgets shared across cloud and edge gateways.
Private GatewayPrivate LLM Edge Gateway
Run the same AI governance engine inside your own VPC — guardrails, budgets, and audit enforced locally, with locally encrypted credentials, signed policy snapshots, and budgets shared with every other gateway.
Guardrails & Caching
Cost and safety controls that run on the hot path, priced and audited like any other policy.
AI Guardrails on the Request Path — Secrets, Personal Data & Provider Safety Scans
Protect prompts and responses on AI gateway traffic with built-in credential detection, your own personal-data rules, and optional Azure AI Content Safety, AWS Bedrock Guardrails, Google Model Armor, or webhook scans — with your choice of what happens when a scan cannot run, and an audit trail.
Exact CacheAI Gateway Response Caching — Exact & Semantic Response Cache
Skip the provider round trip and slash LLM spend with policy-scoped exact-match and semantic vector caching. Watch cache hit rates in Monitor only before serving.
Semantic CacheSemantic Vector Response Cache
Serve equivalent — not just identical — requests from a policy-gated semantic cache with similarity matching, a maximum entry age, and answers kept inside the app that stored them.
AgentsAI Agent Cost Controls
Track and govern agent sessions, retries, loops, tool calls, MCP workflows, and autonomous runs before they create runaway AI spend.
Optimization & Intelligence
Resilience and savings you can see — provider failover inside your budget, and an always-on spend feed.
LLM Provider Failover — Automatic Retries and Provider Fallback
Keep model calls working when a provider fails: automatic retries and failover to another provider that serves the same model, with no configuration, under the same budgets and guardrails.
AI IntelligenceAI Spend Intelligence: Anomalies, Findings, and Recommendations
An always-on feed that surfaces LLM spend anomalies, attribution and pricing findings, retry and failure waste, and guardrail-overhead cost directly in the console — ranked by impact.
BenchmarksAI Gateway Latency & Governance Benchmarks (2026)
Measured latency benchmarks for full request-path AI governance: virtual keys, guardrails, atomic budget checks, exact response caching, and guardrail block enforcement across sustained throughput.
Finance & Governance
Turn usage into owned, reportable spend — attribution, unit economics, contract pricing, and shadow AI cleanup.
Model Spend Analytics
Analyze AI spend by provider, model, team, app, environment, user, session, run, and custom business dimensions.
Unit EconomicsAI Unit Economics
Measure LLM cost per customer, workspace, agent run, ticket, document, transaction, and product workflow.
Contract PricingContract Pricing and Enterprise Rate Overrides
Apply forward-only customer- or org-specific contract rates, commitments, and credits on top of list pricing, with a server-authoritative preview before approval and an immutable audit history behind every override.
Shadow AIShadow AI Discovery
Find unowned LLM usage, direct provider calls, and AI spend that is not mapped to teams, apps, or approved governance paths.
Supported provider surfaces and model vendors
Govern known model families with canonical policy names, and still allow exact strings for fine-tuned, custom, and newly released models.
Attribution without routing through the gateway
Keep your own provider client, drop in a lightweight SDK, and send usage with custom attribution. JavaScript and TypeScript, Python, and Go.
npm install @cloptima/llm-observability
pip install cloptima-llm-observability
go get github.com/cloptima/llm-observability-goimport { initFromEnv, extractOpenAIUsage } from "@cloptima/llm-observability";
const cloptima = initFromEnv();
await cloptima.observeCall({
provider: "openai",
model: "gpt-5.4-mini",
call: () => summaryService.generate(prompt),
extractUsage: extractOpenAIUsage,
featureId: "summary_generation",
workflowId: "support_agent",
// + team, environment, tenantId, costCenter, and custom metadata
});Telemetry posts to https://api.cloptima.ai/v1/ai/integrations/sdk/events. Missing config falls back to a disabled pass-through, so local dev and tests never break. Read the SDK guide →
Onboarding guides
Provider connections, gateway adoption, SDK attribution, and OpenTelemetry ingest.
OpenAI-Compatible AI Gateway for FinOps
Get model governance, cost attribution, and budget controls without a large application rewrite.
Connect your AI stack · 6 min readConnect OpenAI Usage to Cloptima
Route OpenAI-compatible traffic through Cloptima for model access control, spend attribution, and budget enforcement.
Connect your AI stack · 6 min readConnect Anthropic Usage to Cloptima
Track and govern Anthropic usage with team attribution, model policies, and AI FinOps reporting in Cloptima.
Connect your AI stack · 7 min readConnect Gemini and Vertex AI Usage to Cloptima
See model-level analytics and budget controls for your Google AI spend.
Connect your AI stack · 7 min readConnect Amazon Bedrock Usage to Cloptima
Track and govern Bedrock model spend with AI FinOps attribution and budgets.
Connect your AI stack · 7 min readLLM FinOps for Vercel AI SDK Apps
Add model spend attribution and gateway governance to your TypeScript AI apps.
AI FinOps options
Cloptima vs LiteLLM
Compare Cloptima and LiteLLM for AI gateway governance, guardrails, budgets, MCP tool control, caching, and AI spend attribution.
Cloptima vs Portkey
Compare Cloptima and Portkey (Prisma AIRS AI Gateway) for AI gateway governance, guardrails, budgets, MCP tool control, and AI spend attribution.
Cloptima vs Helicone
Compare Cloptima and Helicone for AI gateway governance, guardrails, budgets, LLM observability, and AI spend attribution.
Cloptima vs Langfuse
Compare Cloptima and Langfuse for AI governance, guardrails, budgets, LLM observability, prompt management, and AI spend attribution.
AI Gateway vs AI FinOps
Understand the difference between AI gateway operations and AI FinOps control planes for model spend governance.
Cloptima vs OpenRouter
Compare OpenRouter's multi-model access and team guardrails with Cloptima's governed AI gateway: policies, guardrails, budgets, BYOK, tool control, and spend attribution.
Cloptima vs Cloudflare AI Gateway
Compare Cloudflare AI Gateway's edge proxy, guardrails, and spend limits with Cloptima's governed AI gateway: policies, data protection, tool control, budgets, and spend attribution.
Cloptima vs Bifrost
Compare Cloptima and Bifrost (Maxim AI) for AI gateway governance, guardrails, MCP tool control, budgets, and spend attribution.
Cloptima vs Kong AI Gateway
Compare Cloptima and Kong AI Gateway for LLM governance, guardrails, budgets, MCP tool control, and AI spend attribution.
Cloptima vs TrueFoundry
Compare Cloptima and TrueFoundry AI Gateway for AI governance, guardrails, budgets, MCP tool control, and spend attribution.
By team
AI Spend Governance for Engineering Leaders
Give engineering leaders one operating model for LLM access, budget controls, ownership, and AI feature cost accountability.
FinOpsLLM Chargeback and Showback
Allocate LLM spend to teams, apps, environments, customers, and product workflows with attributed records.
Platform TeamsAI Gateway Governance for Platform Teams
Give developers governed model access while platform teams manage provider credentials, virtual keys, model policies, budget limits, and audit trails.
AI AgentsAI Agent Cost Control
Track and control LLM spend from agent sessions, retries, loops, tools, and long-running autonomous workflows.
FinanceAI Margin Reporting
Connect LLM spend to customer, workflow, and product context for better AI feature margin visibility.
GovernanceShadow AI Discovery for Governance Teams
Find unowned model usage and direct provider calls that bypass approved AI spend and access governance.
Questions teams ask
Put your first governed call through in five minutes
Point your SDK at the gateway, bind a policy, and watch the first call land on the ledger.